YAML DAGs Become More Useful When AI Writes the Code
The Old Pitch Is Gone
Defining Airflow DAGs in YAML is not new. With dag-factory, for example, a DAG looks like this (its docs also have a side-by-side comparison of the same workflow in Python and in YAML):
etl:
  default_args:
    owner: data-team
    start_date: '2026-01-01'
  schedule: 0 3 * * *
  tasks:
    - task_id: extract
      operator: airflow.providers.standard.operators.bash.BashOperator
      bash_command: "python extract.py"
    - task_id: transform
      operator: airflow.providers.standard.operators.bash.BashOperator
      bash_command: "python transform.py"
      dependencies: [extract]
For years, the pitch for tools like this was simple: build DAGs without knowing Python, and without learning Airflow primitives. AI made this reason much weaker. Now an analyst who cannot write Python just asks an agent, and gets a working Python DAG in a minute. So if “you don’t have to write Python” is the only reason to use YAML, people can fairly decide these tools are no longer needed.
I don’t think the answer is to say that AI-written Python is not good enough yet. That claim gets weaker with every model release. I think a better answer is this: even if AI writes perfect Python, a team with many DAGs and many authors still wants a workflow definition layer. When an agent writes the code, writing is not the expensive part anymore. Reviewing it, checking it, and changing it later are. So we should choose the format for those jobs. AI sits upstream of a YAML tool, not opposite it.
This is not only an Airflow question. There is already discussion about whether to use a DSL or general-purpose code with LLMs, and the idea is the same: a small language with a validator gives the model clear boundaries, and lets it fix its own mistakes, as long as the language stays small. To be clear, I am not saying YAML is always better than Python. My point is narrower: for teams with many DAGs, YAML becomes more useful when AI writes the code. I see three reasons for it. It is constrained, it is verifiable, and it is easier to maintain at scale.
Constrained: A Workflow Does Not Need to Be a Program
A Python DAG is a program, and an agent writing a program can do anything. It can put code at the top level of the file, create tasks in a loop, import helpers from anywhere, or call an API while the file is being parsed. Airflow parses DAG files again and again, so a slow call at the top level slows down the whole scheduler. Also, if you ask an agent for ten DAGs, you get ten slightly different styles, depending on the prompt and the model. Each of these choices is something a reviewer has to notice.
A YAML DAG has much less room for these choices. The schedule is always under schedule, the tasks are always a list under tasks, and the dependencies are always a list on each task. An agent cannot put a slow API call at the top level, because there is no top level to put it in. Of course it still makes mistakes, but the mistakes are inside a small, fixed structure. Give AI a workflow language, not an entire programming language.
This does not mean Python goes away. I believe most DAGs will split into two layers: Python for the logic inside each task, and a small declarative format for the workflow around it. The functions that clean data, call APIs, or train models stay in Python. The schedule, the tasks, the dependencies, and the retries move to a format that agents write and machines check. Other tools already work this way. dbt keeps the logic in SQL and the model properties in YAML. Jenkins has a structured Declarative Pipeline syntax, where free-form code in a script step is only an escape hatch.
Verifiable: Checked Before It Reaches Airflow
YAML has a fixed grammar, so it can be checked without running anything. A rule like “every DAG has an owner”, “no BashOperator in production”, or “memory request under 4G” is a few lines of code over a YAML tree. The same rule over Python needs AST analysis, and it still misses DAGs that are built dynamically. Writing code got much faster with AI, but review did not, so review became the bottleneck. Every rule a machine can check is review work that a senior engineer no longer has to do.
It also lets the agent check its own work, before any person looks at it.
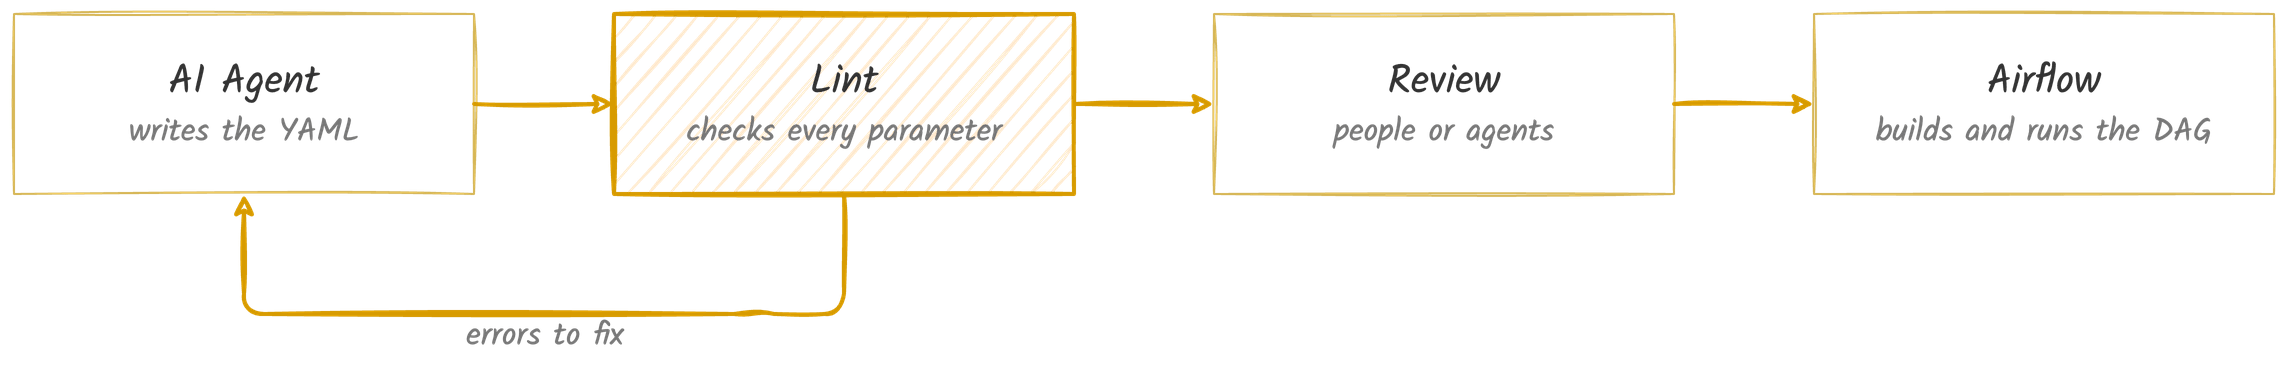
The agent writes the config, a validator checks it, and the errors go back to the agent until the config is valid. This only works well if the error messages use the terms of the workflow. A stack trace from Airflow’s DAG parser is written for a person who debugs Python code. An error like “task transform depends on extrac, which does not exist” is something an agent fixes right away. In my opinion, the error message is now a product feature, and its main user is a machine.
dag-factory has this kind of validator in its dagfactory lint command. It checks each DAG against a table of every parameter dag-factory accepts: unknown keys, wrong types, parameters the installed Airflow version does not accept, missing dependencies, and cycles. For example, if the DAG above has a typo in a dependency, lint reports:
error: [etl.tasks.transform.dependencies] `transform` depends on `extrac`, which does not exist.
Maintainable: Keep the Whole Fleet Up to Date
The third reason is that YAML DAGs are easier to keep up to date, because a tool can change the whole fleet at once. dag-factory’s convert command already does a fleet-wide migration from Airflow 2 to Airflow 3, like updating the import paths of the standard operators. Because every config has the same structure, this rewrite is deterministic: the same input always gives the same output, and lint can check the result.
Doing the same over Python DAGs is not reliable. Each Python file can build its DAG in its own way, so a tool cannot safely rewrite all of them. An agent can do the migration, but an agent is not a deterministic tool. It may change each file in a slightly different way, and each change has to be checked like new code. With YAML, the tool does the migration, and the agent and the reviewers only need to handle what the tool cannot.
Choosing Between Python and YAML
The same debate is happening in infrastructure as code, between declarative formats like HCL and tools that use general-purpose languages. The argument for general-purpose languages is a strong one: a real language works with the testing frameworks, IDEs, and coding agents developers already use, so AI output is easier to verify. In CI/CD, there is a similar complaint that a big YAML file has no functions, no abstraction, and no debugger.
To be honest, both are fair points. But I think they answer a different question. Unit tests check that the code works. They do not check that the workflow follows the platform’s rules, like every DAG has an owner. And when an agent writes the DAG, it usually writes the tests too, so the tests are also generated code that someone has to review. The “big YAML” problem is real as well, but it is a sign that the format has grown too much. A YAML tool for the AI era should stay small, and leave the hard cases to Python.
So the choice depends mostly on how many pipelines you have, and how many people, or agents, write them.
| YAML fits better when | Python fits better when |
|---|---|
| You have many DAGs and many authors | You have a few DAGs and one small team |
| Most pipelines follow a few repeated patterns | Each pipeline has its own unusual structure |
| You want policy checks before anything reaches Airflow | Reading the code in review is enough |
| You need changes across the whole fleet | The DAG structure depends on complex logic or external systems |
For a team with five DAGs, AI-written Python is fine, and YAML is one more layer to learn. But the more DAGs a team has, the more useful YAML becomes when AI writes them. In a company with hundreds or thousands of DAGs, written by many teams and many agents, writing them is the cheap part. The hard part is keeping all of them correct, consistent, and up to date. And this is where a constrained, verifiable, and maintainable format helps the most.